
What Is Model Quantization?
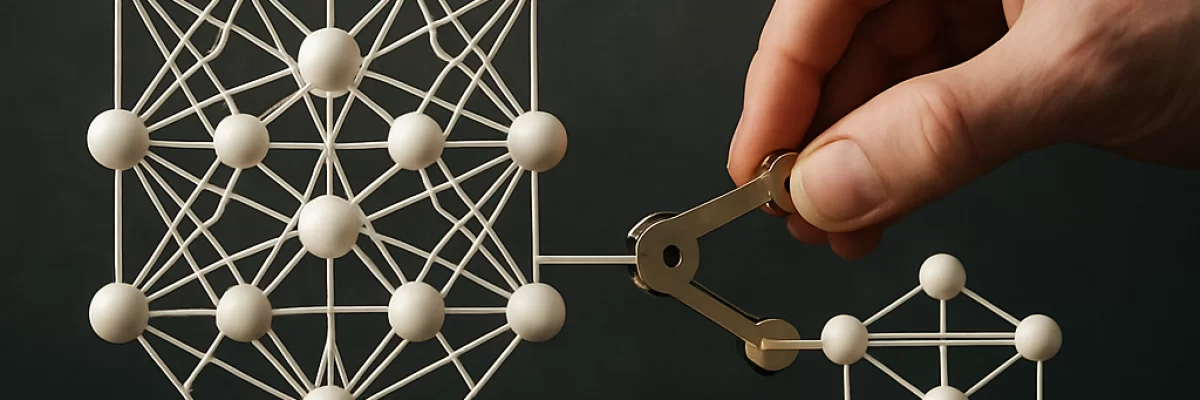
Model quantization in simple terms
A neural network contains many numerical values. Weights store learned parameters, while activations are intermediate values produced as the model processes an input. In the original model, these values may use relatively high-precision formats.
Quantization converts some of those values into a representation that uses fewer bits. A lower-bit representation can require less memory and storage, and it can reduce the amount of data that must move through a system during inference. The model’s architecture does not necessarily change; the numerical representation used to run it changes.
A useful way to think about quantization is rounding a detailed measurement to a smaller set of permitted values. The rounded value takes less information to store, but it may not preserve every detail of the original. Quantization systems try to limit the error introduced by this conversion, especially in values that are important to the model’s output.
Why quantization matters for AI models
Large models are often constrained by memory capacity, memory bandwidth, storage size, and computational cost. A model may be useful in principle but too large to fit comfortably on a particular GPU, CPU, mobile device, or local computer.
Quantization can help by making the model’s stored representation smaller. For large language models, lower-bit weight representations are widely used to make local inference and parameter-efficient fine-tuning more practical. Quantization can also reduce serving costs or allow a larger model to run with fewer devices.
These benefits are not automatic. A quantized model is faster only when the hardware, runtime, and numerical kernels can process its format efficiently. Speed can also depend on batch size, sequence length, memory access patterns, and the particular workload. A format that saves memory may provide little speed improvement on hardware that does not support it well.
How quantization works
At a high level, quantization maps values from a larger numerical range to a smaller set of representable values. The mapping is described using metadata such as a scale and, in many approaches, a zero point.
The scale describes how far apart the representable values are. The zero point helps align the quantized range with the original values, particularly when the values are not centered around zero. During computation, a system may use the compact values directly or convert them back to a higher-precision form for particular operations.
Quantization can be applied at different granularities. A system might use one mapping for a large group of values or separate mappings for smaller groups, channels, or other portions of a tensor. Finer-grained mappings can preserve accuracy better, but they require more metadata and may be more complicated to execute efficiently.
Weights and activations
Weight-only quantization changes the stored learned parameters while leaving more of the runtime computation in a higher-precision format. This is common in large language model workflows because weights occupy a substantial amount of memory.
Activation quantization also represents intermediate values with lower precision. It can reduce the cost of more of the computation, but activations can be more difficult to quantize reliably because their ranges depend on the input and the model’s internal behavior.
A model can use different precision levels for different parts of the system. Quantization is therefore not simply a choice between “quantized” and “not quantized”; it is a set of decisions about which values use which representations and how those representations are handled.
Post-training quantization and quantization-aware training
Post-training quantization
Post-training quantization, often abbreviated PTQ, converts an already-trained model without retraining the entire model from the beginning. It is attractive because it can be applied after training and usually requires less training work than changing the model’s training process.
Many PTQ workflows use calibration. Calibration passes representative inputs through the model to estimate useful value ranges and identify how numerical values should be mapped. The quality and representativeness of the calibration data can affect the final result, especially when activations are quantized.
Quantization-aware training
Quantization-aware training, or QAT, exposes the model to the effects of lower-precision computation during training or fine-tuning. The model can then adjust its learned parameters to reduce the impact of quantization.
QAT may preserve accuracy better for some workloads, but it requires an appropriate training or fine-tuning process. PTQ is often simpler to apply to an existing model, while QAT can be more involved but gives the model an opportunity to adapt to the intended numerical representation.
Common quantization terms and methods
Quantization terminology varies between tools and model formats, so names should not be treated as interchangeable.
- Bits: The number of bits used to represent a value or group of values. Fewer bits generally mean a smaller representation, but they can also increase approximation error.
- Calibration: Measuring value ranges or other statistics, usually with representative inputs, to guide quantization.
- GPTQ: A post-training weight-quantization approach designed for very low-bit compression of generative transformer models. It uses an approximation of second-order information to reduce the effect of quantization errors.
- AWQ: A weight-quantization approach that uses activation statistics to identify more important channels and protect their behavior through scaling.
- bitsandbytes: A commonly used software workflow and library integration for loading or working with lower-bit model representations. It is distinct from methods that require a model to be pre-quantized in a particular format.
- FP8: An eight-bit floating-point representation. Unlike an integer format, it retains floating-point characteristics, but its usefulness depends on hardware and runtime support.
Tools may quantize a model in advance or quantize it when the model is loaded. A pre-quantized GPTQ or AWQ model, for example, is not the same workflow as loading a higher-precision model through a library that performs quantization during loading. Runtime support and available operations can differ by method.
What are the tradeoffs?
The main advantage of quantization is efficiency. A smaller representation can reduce memory use, storage requirements, and data movement. This may make a model fit on hardware where the original version would not, or allow more models and larger workloads to share a system.
The main cost is approximation. Lower-precision values cannot represent every detail of the original values, so quantization can reduce accuracy or change model behavior. The impact may be small for one task and more noticeable for another. Weight-only and activation quantization can also introduce different tradeoffs.
There are additional practical considerations:
- A lower-bit format does not guarantee faster inference.
- Hardware support can matter as much as the nominal bit width.
- Different runtimes may support different quantization methods and operations.
- Calibration data can affect the behavior of activation-quantized models.
- Extra scaling metadata and conversion steps can reduce some of the theoretical savings.
- A quantized model may need a format-specific loader or runtime rather than the same process used for the original model.
Does quantization make a model smaller?
Usually, quantization reduces the storage needed for the values being quantized, especially weights. But the final file size depends on more than the headline bit width. Metadata, unquantized layers, model files, and the way values are grouped all contribute to the result.
Quantization is also different from pruning. Pruning removes or ignores some connections, while quantization keeps the model’s values but represents them with fewer bits. The two techniques can be combined, but they solve different problems.
How to evaluate a quantized model
Do not judge a quantized model only by its file size. Compare it with the original model on the tasks that matter to you.
- Check whether the quantized format is supported by your hardware and runtime.
- Measure memory use during the actual workload, not only the model file size.
- Compare response quality on representative prompts or evaluation data.
- Measure generation speed, latency, and throughput under realistic settings.
- Check whether the model’s important operations are supported without unexpected conversions.
A small model that runs reliably may be more useful than a more aggressively quantized model that saves memory but produces unacceptable results or receives little hardware acceleration.
What quantization means for beginners
If you are experimenting with local language models, quantization is primarily a way to match a model to the resources available on your computer. Start by identifying how much memory your workload can use, then choose a model format supported by the runtime you plan to use. Test quality and speed rather than assuming that the lowest-bit option is automatically the best.
For a general understanding of deployment choices, it can also help to compare local LLMs and cloud LLMs. Quantization is especially relevant to local deployment, but cloud services may use quantization internally as well; users may not always control or see that implementation detail.
The key idea
Model quantization is a controlled reduction in numerical precision. It can make neural networks more practical to store and run by reducing memory and data movement, but it may introduce accuracy loss and does not guarantee a speedup. The right choice depends on the values being quantized, the quantization method, calibration or training procedures, and the hardware and software that execute the model.